Sacred VM Meme Goes Viral: The Fatal Danger of Sudo Rebooting Old Uptime Servers Revealed!

Direct Answer Box – Executive Summary:
- Excessively long server uptime (thousands of days) is not a sign of stability, but rather a time bomb as outdated configurations and software libraries accumulate.
- A viral meme from @kuliserver highlights the fatal risks of “sudo reboot” on “Sacred VMs” using no longer supported OS and app stacks (e.g. Ubuntu 18.04 and Python 2.7).
- Boot failure after long uptime often leads to a “Legacy Infra Disaster,” which ends in a total service outage and administrative panic.
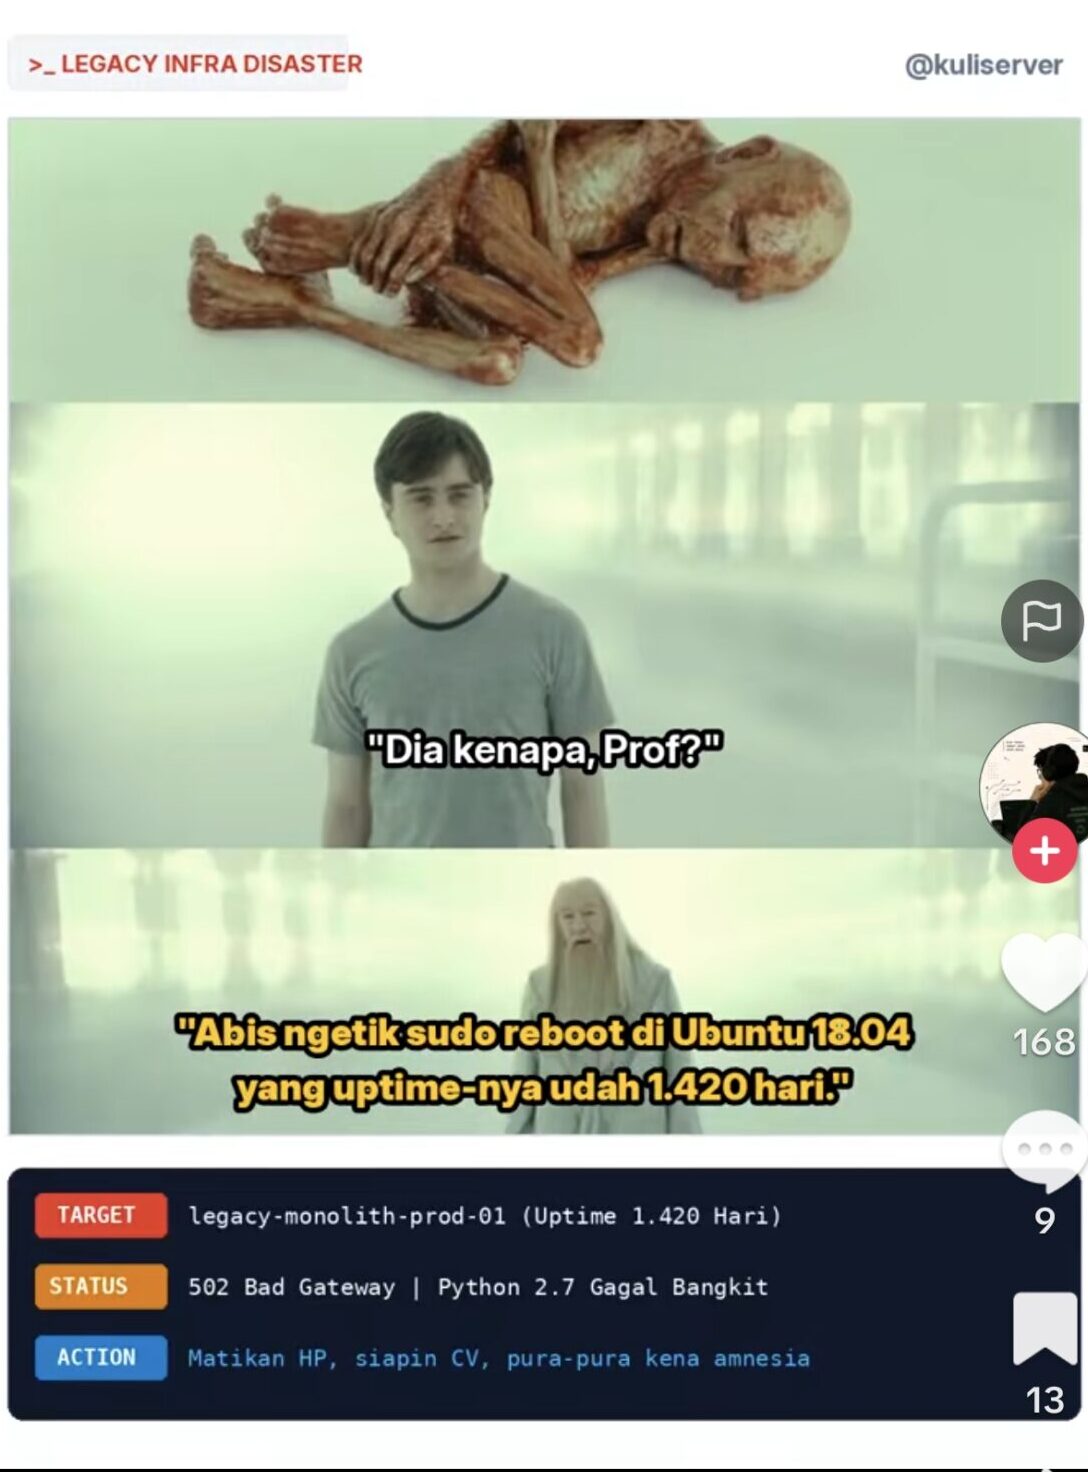
A humorous meme mixed with technical horror has recently gone viral on social media platforms, particularly among the SysAdmin and DevOps communities. The image, shared by the TikTok account @kuliserver (seen in the screenshot), uses an iconic scene from the Harry Potter films to illustrate a system administrator’s greatest fear: performing a sudo reboot on an old server.
The editors of lidahtekno.com observed that this meme is not only funny, but also holds a harsh truth about the technical debt that plagues many office infrastructures. The meme depicts a destroyed Voldemort, with Dumbledore explaining to Harry that his condition was caused by a simple action: “After typing sudo reboot on Ubuntu 18.04, which has an uptime of 1,420 days.”
Why Is Long Uptime a Time Bomb?
Among novice technicians, long uptime is often mistaken for a system’s reliability. However, for a Senior Technology Journalist at lidahtekno.com, thousands of days of uptime is a very high-risk indicator.
The reason is simple: a server that has been running continuously for years may have experienced thousands of minor configuration changes directly (in-memory) without ever being tested for a full boot process. This problem is known as “configuration drift.”
Anatomical Dissection of Disaster Memes @kuliserver
Adapted from the editorial team’s analysis of the technical details in the meme, here are the details of why the server was destroyed to pieces:
Target Analysis: legacy-monolith-prod-01 (Uptime 1,420 Days)
An uptime of 1,420 days means this server hasn’t been restarted in nearly four years. This means the operating system (kernel), drivers, and core libraries have never been safely updated through a reboot. All application state resides solely in memory (RAM), and a reboot will completely erase it.
Trigger Factor: Sudo Reboot on Old OS and Stack
According to Canonical’s official release, Ubuntu 18.04 (Bionic Beaver) has reached the end of standard support in April 2023. Python 2.7 software has also been sunset since January 2020. Trying to restart a process on an outdated technology stack is a recipe for catastrophic failure. Corrupt library dependencies, which are not detected while the process continues to run, will appear on reboot and prevent applications from “waking up.”
Final Result: 502 Bad Gateway and Python 2.7 Failed to Restore
The error message “STATUS: 502 Bad Gateway” is clear evidence that the server failed to serve the request, because the application process behind it (Python 2.7) failed to restart.


Comparison: Modern vs. Legacy Infra
The following table provides a comparative overview between the modern approach and the legacy infrastructure risks depicted in the meme:
| Characteristics | Modern infrastructure (Cloud Native/CI/CD) | VM Keramat (Legacy Infra Disaster) |
|---|---|---|
| Architecture | Microservices, Stateless | Monolithic, Stateful |
| OS/App Updates | Automatic, routine, sandbox tested | Manual, rare, scary |
| Resilience | Tolerant to component failure, easy to replace | Prone to total failure from a single point |
| Uptime | Dynamic uptime, pods are replaced frequently | Thousands of days of uptime (both pride and fear) |
| Disaster Recovery | Automatic, minimal recovery time | Very difficult, requiring intensive manual intervention |
Action Guide to Taming the “Sacred VM”
Lidahtekno.com warns: don’t follow the hilarious advice from memes (“Turn off your phone, prepare your resume, pretend you have amnesia”). Instead, if you’re managing a “sacred VM,” follow this safety checklist:
- Complete Dependency Audit: Note any software, libraries, and configuration files used. Ensure all service files (such as systemd) are configured for boot-start.
- Reboot Test in Sandboxing Environment: Try replicating the sacred VM into an isolated testing VM and rebooting there first to see what’s broken.
- Perform a Comprehensive Backup/Snapshot: Ensure you have a valid hypervisor-level snapshot and application data backup before attempting a native server reboot.
- Stop In-place Updates: Do not attempt to perform a dist-upgrade directly on a production server.
- Create a Phased Migration Plan: Create a new VM with a modern OS and supported stack, then migrate application workloads incrementally.
Instead of boasting thousands of days of uptime, the editors at lidahtekno.com urge technicians to focus on building resilient, automated, and easily recoverable infrastructure. This viral meme is a stark reminder that technical debt, left to accumulate, will sooner or later demand payment in the form of a painful total service outage.